Private AI in Singapore

AI on infrastructure you control

For Singapore organisations whose data should not go to a public AI service. Run private AI models in your own cloud account, in your data centre, or on hardware in your office. You choose how much you own. We set it up, connect it to your systems and hand it over working.

What is private AI?

Private AI means running AI models, often called a private or self-hosted LLM, in an environment your organisation controls: your own cloud account, your data centre, or hardware on your premises (an on-premise LLM). Your data is processed there instead of being sent to a shared public AI service, and you decide who can access it. When that environment is also in Singapore, under your control, it is often called sovereign AI.

Last reviewed

Your Choice

Choose your level of control

All three run private models that only your organisation uses. The difference is where the compute sits and who owns it.

Your cloud

In your cloud account

GPU capacity in your own AWS, Azure or private-cloud account, set up in your name from day one, so there is nothing to hand over later.

You control
  • The account, billing and access
  • The region your data is stored in
  • Who can see and change the system
Best forGetting started quickly, with no hardware to buy and capacity that grows with use.
Your data centre

In your data centre

GPU servers you own, racked in your data centre or a colocation facility you lease, on your own network.

You control
  • The hardware itself, as your asset
  • The network and facility it runs in
  • Physical and logical access
Best forOrganisations with existing facilities, high uptime needs, or many sites served from one place.
Your premises

On your premises

Compact AI units installed in your office or branch, beside the cameras, sensors and people that use them.

You control
  • Everything in the other options
  • The building the data never leaves
  • Whether anything connects outside at all
Best forData that must stay on site, local cameras and sensors, and sites that must keep working offline.

Mix them, for example devices at each branch with GPU servers in your data centre. The same open models and API run in all three, so you can start in your cloud and move later.

On Your Premises

Two ways to run it on site

Both run the AI inside your building with no internet needed to answer a question. The choice comes down to how you want to grow, and the space you have.

Start small: compact AI boxes

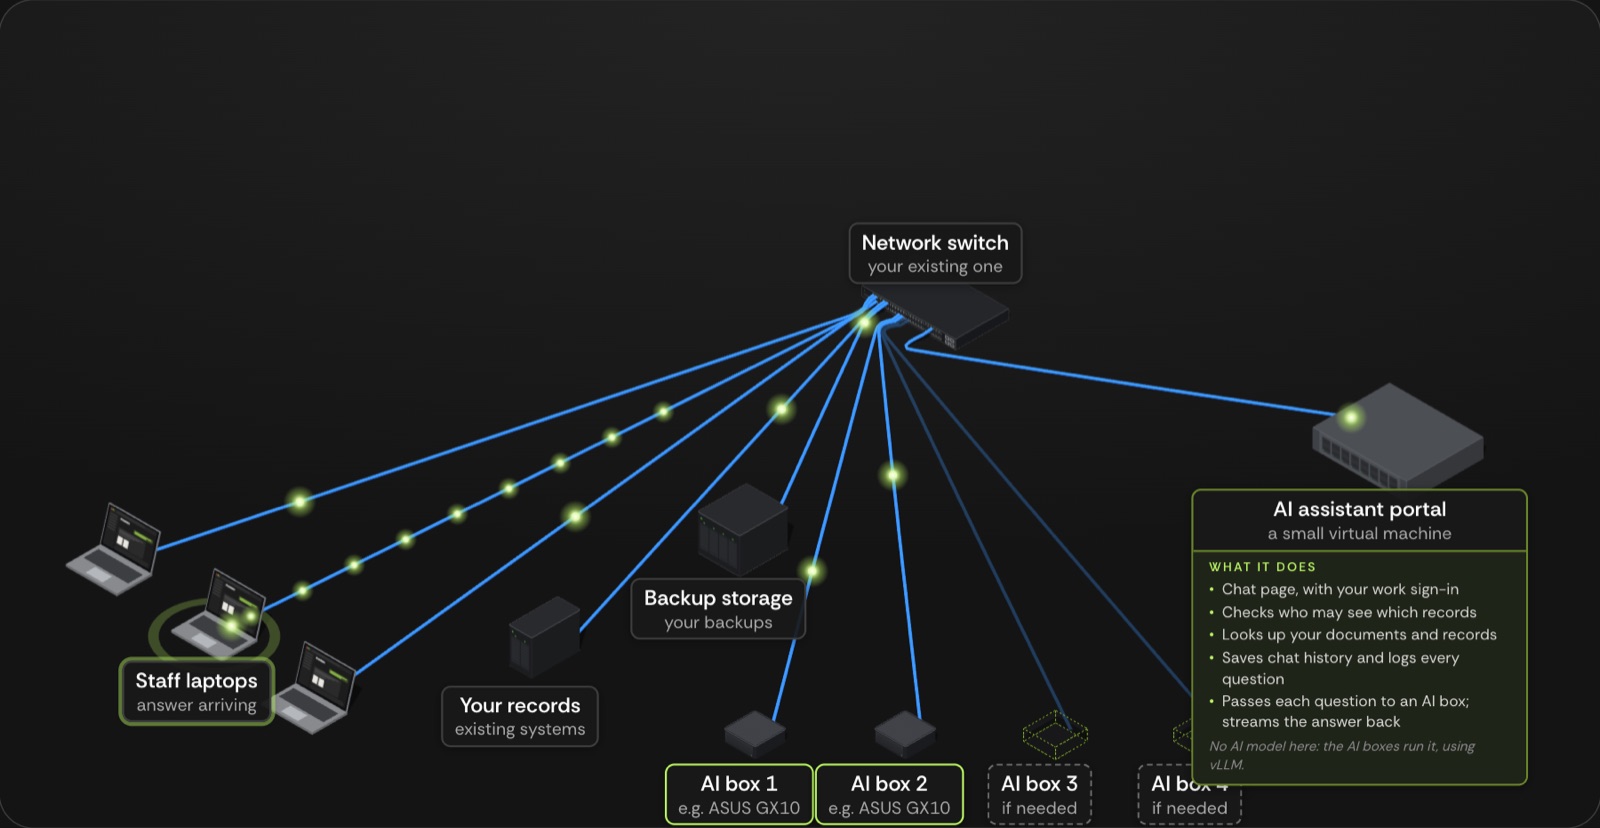
A small virtual machine on your servers runs the chat page and checks permissions. It keeps each conversation on one AI box and gives new ones to the least busy box, so one box failing does not stop the service.

Example question · finance team

What payment terms did we agree with our main supplier this year?

Net 45 days, from the contract renewed in March. The contract and the approval email are linked below.

The answer shows its sources. The log stays on your system.

The two dashed boxes are added only if the pilot shows you need them.

Start small

Compact AI boxes, added as use grows

Begin with one desk-sized AI computer, such as an NVIDIA DGX Spark or a partner version like the ASUS Ascent GX10. We measure real demand in a pilot, then add boxes only when you need them.

  • Each box runs its own copy of the model, and the boxes share the load
  • If one box fails, the others keep serving
  • Extra boxes usually arrive within one to two weeks
  • Sits on a shelf: no rack or server room needed
Start big

One rack server with a professional AI card

A rack-mount server, for example a Dell PowerEdge with an NVIDIA RTX PRO 6000, for the most headroom and the larger open models from day one.

  • One server runs everything, so it is simple to manage
  • Onsite manufacturer warranty, such as next-business-day repair
  • Needs a rack, a UPS and a cooled server room
  • If the server fails, the service pauses until it is repaired

We can procure the hardware for you, or you can buy it directly. Either way, it is your asset from delivery.

Why Private AI

Why organisations keep AI in their own hands

Confidentiality

Client files, recordings and regulated records stay in an environment you control, which supports your data-protection and client obligations.

Costs you can see

In your cloud, usage is billed straight to your own account. On-premise, it's a one-off hardware purchase instead of fees per request.

Keeps running offline

On-premise installations carry on through internet outages and catch up when the connection returns.

No lock-in

Accounts in your name, hardware as your asset, and a handover that lets your team run it without us.

In Singapore

What Singapore's rules say about where data goes

Rules that shape where sensitive data may be processed. Your compliance team decides what each kind of data needs; we build to that.

Public sector

Government agencies may use GenAI services with models hosted overseas only for data up to RESTRICTED and SENSITIVE NORMAL, and models hosted in Singapore for data up to CONFIDENTIAL and SENSITIVE HIGH. Self-hosted models must sit in an environment cleared for the most sensitive data they hold. A useful benchmark for anyone handling sensitive data.

Source: GovTech GenAI policy

Financial services

MAS's Guidelines on AI Risk Management, issued 7 October 2026 and in effect from 7 October 2027, keep a financial institution primarily accountable for the third-party AI it uses, including limiting, suspending or replacing a provider whose risks it cannot contain.

Source: MAS guidelines

Personal data

Section 26 of the PDPA limits transfers of personal data outside Singapore unless the organisation ensures protection comparable to the PDPA. AI that runs in Singapore keeps that data in the country.

Source: PDPC guidelines

Healthcare

The Health Information Act, passed in January 2026 and expected to take effect in early 2027, requires licensed healthcare providers to share key patient information with the national health record and to meet cybersecurity and data-security requirements.

Source: MOH announcement

General information, not legal advice.

Compare

Private AI or ChatGPT Enterprise?

Public AI services suit a lot of everyday work. Private AI is for the data and workflows that need more control.

QuestionChatGPT Enterprise or Microsoft 365 CopilotPrivate AI with InitD
Where your data is processedOn the provider's servers. OpenAI can store ChatGPT Enterprise data at rest in Singapore; Microsoft offers no in-country data residency for Copilot in Singapore.In your cloud account's Singapore region, your data centre or your building.
Which modelsThe provider's own models, among the most capable available.Open models you choose, such as Llama, Qwen, Mistral or SEA-LION, benchmarked on your work.
When things changeThe provider updates models and terms on its own schedule.Nothing changes until you approve it.
Without internetDoes not work.Keeps working when it runs on your premises.
How you payA licence per user, per month.A fixed set-up figure, then cloud usage or hardware you own. No per-user licences.
If you stopYou export your data; the service stays with the provider.You keep the system, the models and the data.

Many organisations use both: a public service for everyday work, and private AI for confidential data and core workflows.

What You Get

A working private AI system that your team can run

One accountable partner from assessment to handover. You don't coordinate cloud consultants, hardware suppliers, installers and developers yourself.

  • Infrastructure set up where you chooseConfigured in your cloud account, or hardware supplied and installed at your location.
  • AI set up for your use casesDocument search, drafting, analysis of images or recordings, assistants for staff.
  • Your systems and people connectedStaff use it inside the tools they already have.
  • Proven on your own dataMeasured before acceptance, against tests you agree.
  • Your team trained and documentedWith optional ongoing support from InitD.

Privacy At Each Step

How a question is answered

A member of staff asks the assistant a question about your own records. Every step happens inside your environment.

Always: your data never trains the models, and updates are installed only in windows you agree.

  • Sign in with your work accountMicrosoft 365 or Google sign-in, with access set by role.
  • Ask in plain EnglishNo public AI service is involved. On your premises, it works with no internet.
  • Look up your recordsOnly the documents and data this person is allowed to see.
  • Answer with its sourcesSources are shown, so staff can check the answer.
  • Log kept on your systemYou set how long questions and answers are kept, and they are backed up.

Before You Decide

Questions your board will ask

Straight answers to the questions that decide private AI projects.

What does it cost?

Set-up is a fixed figure agreed before you commit. It depends on the size of the models, how many people use the system at once, where it runs and how much uptime you need. In your own cloud, running costs are billed directly to your account. On-premise, hardware is a one-off purchase you own, with the supplier warranty documented before anything is ordered.

Who owns it?

You do. Cloud accounts are in your name from day one, and on-premise hardware is your asset. Your data and applications remain yours.

Is our data safe?

It stays in your environment and is never pooled into a shared public AI service. On-premise, raw data never leaves the building.

What if the hardware fails?

On-premise, the manufacturer warranty covers parts. We diagnose the fault, handle the warranty claim and reinstall the repaired unit for you. With several compact AI boxes, the others keep serving in the meantime; a single rack server comes with an onsite warranty, such as next-business-day repair.

What if InitD is no longer around?

Your team keeps running it. Handover includes administrator access, setup records and step-by-step operating guides. Ownership of the code we write is set out in the contract.

How long does it take?

Set-ups in your own cloud are quicker; on-premise adds a site survey and hardware lead times. Every project runs a pilot with a small group of staff before it goes live for everyone. You get a timeline together with the fixed figure.

More questions about private AI

Can we run ChatGPT-style AI on our own servers?

Yes. Open models can handle drafting, summarising, document search and image analysis on your own servers or in your own cloud account. We benchmark them on your real work first, so you know what to expect before you commit.

Can the GPU servers sit in our own data centre?

Yes. We size and source rack-mount GPU servers, configure them ready for your racks, and install them in your data centre or a colocation facility you lease, working with the facility's on-site technicians where needed. The servers are your asset, on your network, with the same private API and handover as any other option.

What is the difference between private AI in our cloud, our data centre and on-premise?

All three run private models that only your organisation uses. In your cloud account there is no hardware to buy and capacity can grow with use. In your data centre you own the servers and get enterprise power, cooling and security. On your premises the data never leaves the building and the system can keep working offline.

Why not ChatGPT Enterprise with Singapore data residency?

For everyday work it may be enough. OpenAI's Singapore option stores your data at rest in Singapore, while the models run on OpenAI's servers, on its terms. Private AI suits data your rules keep off third-party services, work that must continue offline, and cases where you want to choose and fix the model. Many organisations use both.

Is a self-hosted LLM PDPA compliant?

Compliance depends on how you collect, use and protect personal data, not only on where the model runs. Self-hosting makes some obligations easier to meet: when processing stays in Singapore, the PDPA's limits on transfers overseas do not arise for that work, and access, retention and audit logs stay under your control. Your data protection officer sets the requirements; we build to them.

Which open models do you use, and are they good enough?

We choose per task from open models such as Llama, Qwen, Mistral and Gemma, and AI Singapore's SEA-LION, built for Southeast Asian languages. For drafting, summarising, document search and data extraction they often come close to the leading public services; for the hardest reasoning they still trail. We benchmark candidates on your own work before you commit, so you see the difference yourself.

When does owning the hardware pay off?

When use is high and steady. A 2025 cost-benefit study (Pan et al.) found on-premise deployment broke even against commercial AI services within a few months for small models, around two years for medium models and around five years for large ones, and was mainly worth it for very high volumes or strict data-residency needs. If your use is light or uneven, your own cloud account is usually cheaper. We cost both before you choose.

Can we restrict where the AI model comes from?

Yes. Open models come from many developers in different countries, and we only shortlist models from sources your policy allows. Either way, a downloaded model is a file on your own infrastructure, with no connection back to its developer.

What do you need from us to get started?

A short conversation covers it: where the data the AI should use is kept today, one or two tasks you want help with, the IT security policies that apply, where hardware would sit (a shelf or a rack, power and cooling), whether the system may reach the internet for updates or must be fully isolated, how staff sign in (Microsoft 365 or Google), and who approves the budget and when.

Is private AI the same as sovereign AI?

They overlap. Private AI means the models run in an environment your organisation controls. Sovereign AI adds where: the data and models stay within a country's borders and laws. A private AI system on your premises or in a Singapore data centre is both.

Does our data leave Singapore?

Not unless you choose to send it. On your premises or in a Singapore data centre, prompts, documents and answers stay in that facility. In your own cloud account, we deploy to the provider's Singapore region; AWS and Azure both have one. Optional remote management connects outbound only and carries device health, not your data.

Can it search our own documents?

Yes. The usual pattern, called retrieval-augmented generation (RAG), indexes your files inside your environment and lets the model answer with references to the source documents. Access can follow the permissions you already have, so staff only get answers from documents they are allowed to open.

Can it run without an internet connection?

On your premises, yes. Models, data and the API all run locally, so the system keeps working through internet outages, and it can be fully air-gapped if your rules require it. In a cloud account it needs the network, like any cloud service.

How many staff can one server support?

It depends on the model size, the length of the answers and how many people ask at the same moment, not on headcount: an office has far fewer simultaneous requests than staff. We measure throughput on your own workload during the pilot and size the hardware from those numbers, before anything is bulk-purchased.

Our staff already paste company data into ChatGPT. How does private AI help?

It gives them a convenient assistant that runs in your environment, so confidential work has somewhere safe to go. Blocking public tools on its own tends to push their use out of sight; a private alternative, with a clear policy on what goes where, works better.

How A Project Runs

From assessment to handover

On-premise projects add a site survey, and nothing is bulk-purchased until one unit has been proven at your site.

  1. Step 1: Assess

    What you need AI to do, your data rules and your existing systems.

    A clear brief

  2. Step 2: Choose where it runs

    Your cloud, your data centre or your premises, with a fixed figure.

    A fixed figure

  3. Step 3: Set up or install

    Configured in your account, or hardware installed on site, with sample data only until security, logging and backup are in place.

    A running system

  4. Step 4: Prove it

    A pilot with a small group of staff, with accuracy and speed measured on your own data.

    Measured, not promised

  5. Step 5: Hand over

    Agreed tests passed, team trained, documentation delivered.

    Your team runs it, or we do

Reference design

See how a private AI installation fits together

Networking and GPU compute on site or in your data centre, resilience, data ownership, cameras and microphones, your applications and on-site fine-tuning, with four example use cases.

Explore the reference design
For your IT team

Technical detail

In your cloud account

Your account

Deployed into your AWS or Azure account, or your hosting provider. Accounts in your name from the start, with your team given access as it is built.

Model hosting

Open models on dedicated GPU instances, served with open-source software such as vLLM, or managed model services such as Amazon Bedrock, inside your account in the Singapore region.

Infrastructure as code

Every resource defined in code, so the environment can be reviewed, rebuilt or moved.

In your data centre

Rack-mount GPU servers

From makers such as Dell, HPE or Supermicro, sized and sourced for your models, configured before delivery and racked in your facility or a colocation space you lease.

On your network

Connected over your existing network or private links to your sites, behind your firewalls and monitoring.

Facility and AI, clearly split

Your facility provides power, cooling and physical security; InitD installs and supports the AI stack, with the facility's on-site technicians where needed.

On your premises: what we install

AI compute

Compact GPU workstations such as NVIDIA DGX Spark, with 128 GB of unified memory. NVIDIA rates one unit for models of up to 200 billion parameters, and two linked units for up to 400 billion.

Storage

Local NAS with RAID for documents, recordings and model files, sized to your retention period.

Networking

High-speed switching between compute and storage, connected to your existing network.

Edge devices

Optional. Small computers beside cameras, microphones or sensors, processing data where it's captured.

All options · Keep your application. Change the endpoint.

  • OpenAI-compatible APIApplications built for public AI services can often switch with a configuration change. Features are validated before handover.
  • Open modelsLanguage, vision and embedding models such as Llama, Qwen, Mistral, Gemma and SEA-LION, benchmarked for your use case.
  • Access controlsAuthentication, roles, quotas and an audit log of every request.
  • Fine-tuningOn your data, inside your environment.
  • Health dashboardsLoad, capacity and device status.
# Before: a public AI service
client = OpenAI(base_url="https://api.openai.com/v1")

# After: your cloud or your hardware, same code
client = OpenAI(base_url="https://ai.yourcompany.internal/v1")

Reference architecture (on-premise)

In your cloud account or data centre, the same top three layers run there instead of on local hardware, and devices at your sites connect over your network.

The handover pack

Plan your private AI

Tell us what you need AI to do, where the data must stay and who will run it. We will recommend an option and give you a fixed figure.

Discuss your setup